Programmatic Comparison Pages in 2026: What Our Core-Update Data Says About Bonus & Toplist Templates
What are programmatic comparison pages and why do they matter for iGaming SEO in 2026?
Programmatic comparison pages are templated URLs, bonus toplists, odds grids, 'casino A vs casino B' pages, deposit-method hubs, generated at scale from a shared layout and a database feed rather than written one by one. In 2026 they matter because affiliates can't hand-write hundreds of geo-and-vertical combinations, but Google's helpful-content systems now reassess template quality continuously, not just during named updates.
A programmatic set typically pulls bonus amount, wagering requirement, payment methods and license data from a CMS field group or headless API, then stamps that data into a fixed template for every country, operator or bonus-type combination an affiliate wants to rank for. The economics are obvious: a market team targeting 40 countries times 12 bonus categories times 3 operator tiers is staring at 1,440 potential URLs. No editorial team writes that by hand on a sane budget.
What changed by 2026 is cadence. Since the helpful-content system folded fully into the core update process in 2024, we no longer see a handful of discrete 'HCU' events a year, our lab logs meaningful ranking volatility on programmatic iGaming folders in most months, with sharper spikes around the two or three core updates Google still names publicly. That means a template built in January can start leaking visibility by April without any single dramatic update to point to.
The trade-off is structural, not cosmetic. Scale is the entire business case for programmatic pages, you cannot compete for 'best casino bonuses Ontario' and 'bästa casinobonusar' with the same ten manually written pages. But every page in the set now has to survive a version of the question Google's own quality raters apply to YMYL content: does this specific URL add something only this URL could say, or is it a mail-merge of the page next to it?
How did the 2026 core updates actually affect programmatic bonus and toplist pages?
Across a tracking set of roughly 400 programmatic iGaming URLs on several affiliate domains with comparable authority, pages sharing over 80% boilerplate text with sibling pages dropped an average of low-to-mid double-digit ranking positions through the March and August 2026 core updates, while pages with page-unique testing notes and localized data held flat or gained.
We built the tracking set deliberately across markets with different regulatory pressure, UK, Ireland, Ontario, Brazil and India, pulling weekly SERP positions via rank tracking and cross-referencing with Google Search Console impression data for each URL. The goal was to separate 'the whole domain got hit' from 'this specific template got hit,' which is the distinction most affiliate post-mortems skip.
The clearest pattern: pages where the only variable between URLs was the operator name, same intro paragraph, same FAQ block, same comparison logic, showed the steepest declines. Pages that kept the shared layout but swapped in a reviewer's hands-on withdrawal test, a localized payment method note, or a dated 'last verified' line tracked noticeably better through the same update windows.
I want to be precise about what this data can and can't prove. It's correlation across a sample, not a controlled experiment, Google doesn't publish a 'thin template penalty' line item, and domain-level trust, backlink profiles and even server response times move alongside template quality. What I can say is the pattern held across multiple unrelated domains with similar authority levels, which makes template design a plausible contributing factor rather than coincidence. Treat it as a strong signal to act on, not a proven causal mechanism.
What does a defensible bonus page template look like in 2026?
A defensible bonus page template pairs one shared layout, terms grid, wagering calculator, eligibility checklist, with mandatory unique fields per URL: a reviewer byline, a tested withdrawal timestamp, localized currency and payment detail, and a dated 'last verified' line. Without those fields filled per page, the template is functionally duplicate content regardless of how it's dressed up visually.</p>
Start with a content model, not a design file. List every field that must be unique per URL before a developer touches the template: operator-specific wagering requirement, local currency conversion, region-specific payment rails (Pix in Brazil, UPI in India, Interac in Ontario), and a one-line editorial verdict written by a named reviewer. If a field can be auto-populated from a feed with zero human input, it's data, not editorial value, fine to include, but it can't be the whole page.
Second, timestamp honestly. 'Last verified' or 'last updated' fields are low-effort trust signals, but only if the update is real. We've seen affiliates batch-update timestamps across 300 pages overnight with no content change, that's visible in wayback diffs and in our view is the kind of pattern core updates are specifically weighted to discount, since it mimics freshness without substance.
Third, attach an editorial policy link and reviewer bio to every bonus page, not just the homepage. YMYL review criteria care about who stands behind a claim like '35x wagering, verified.' A byline with a visible author page listing credentials and a methodology link does more for trust signals than another paragraph of generic bonus description.
How do you build a toplist template that survives scaled content scrutiny?
A toplist template that survives scale needs a documented, consistent ranking methodology (not just 'our top picks'), per-entry justification text that changes substance between entries, and structured comparison data in a real table element, not an image or a row of divs. The methodology itself should be a linked, citable page, not a vague footer sentence.
Toplists get flagged more often than standalone bonus pages because the failure mode is visible at a glance: ten near-identical two-sentence blurbs under ten logos. Our volatility data shows toplist URLs with a published, linked methodology page, explaining weighting of payout speed, license tier, game count, and customer support response time, retained rankings better than toplists with no stated methodology, across the same update windows discussed earlier.
Per-entry text matters more than people assume. If entry #3's blurb is entry #7's blurb with the brand name swapped, that's detectable both by Google's systems and, frankly, by any human skim-reading the page. Budget real editorial time for the top 10-15 entries that drive most of the traffic, and accept thinner (but still non-duplicate) treatment for the long tail of entries beyond that.
Finally, keep the ranking criteria stable across a toplist family. If "Best Crypto Casinos" and "Best Crypto Casinos, Canada" use different weighting with no explanation, that inconsistency undercuts the trust case your methodology page is trying to build.
What structured data should comparison tables carry for AI citation and AEO?
Comparison tables should carry Table markup alongside ItemList schema, plus Review/AggregateRating only where a genuine, disclosed rating exists, not a fabricated star average. This combination is what lets AI Overviews, Perplexity and ChatGPT extract row-level facts as a citable snippet rather than skipping the table entirely.
Answer engines pull from structured, machine-parseable sources far more reliably than from prose paragraphs restating a table's contents. In practice that means: use an actual HTML <table> element (not CSS grid divs styled to look like one), mark it up with Table schema where your CMS supports it, and wrap the list of entries in ItemList schema with position, name and URL fields filled correctly.
Where you have genuine, disclosed ratings, not a marketing-invented 4.8/5, AggregateRating schema with a clear count of reviews or an explained scoring methodology adds citation-worthy specificity. Google and most LLM-based answer engines are increasingly cautious about undisclosed or inflated ratings on YMYL content; a scoring methodology you can link to is worth more than the star rating itself.
FAQPage schema on the methodology questions ('how do you rank these casinos,' 'how often is this updated') tends to get pulled into AI Overview answer boxes in our citation tracking more consistently than FAQ schema attached to generic player-facing questions, because it answers the implicit 'can I trust this list' query the model is trying to resolve.
How many programmatic pages is too many for one domain?
Our data doesn't point to a fixed page-count ceiling, it points to a differentiation ratio. Domains publishing 500+ programmatic URLs with thin, swap-only variation underperformed domains publishing 150 URLs with page-specific editorial fields, even when the larger domain had comparable backlink authority. Scale the editorial input, not just the URL count.
Affiliates often ask for a number, 'is 1,000 pages too many?' That framing misses what the update data actually shows. Two domains in our set published similarly sized programmatic folders (roughly 600-700 URLs each) around the same bonus-category taxonomy. One built mandatory unique fields and per-page reviewer notes; the other didn't. The second domain lost visibility on close to half its folder during the August 2026 update window; the first domain's losses were concentrated in a much smaller, identifiable subset of low-value combination pages (obscure country x niche bonus-type intersections nobody searches for).
That last point matters separately from quality: publish programmatic combinations that map to real search demand, checked in Ahrefs or GSC query data, not every mathematically possible permutation your database can generate. A page for "Bitcoin casino bonuses in Liechtenstein" that gets zero impressions a month isn't a ranking risk exactly, but it's crawl budget and editorial attention spent on nothing, and large volumes of zero-demand URLs can drag down a domain's average page-quality signal in aggregate.
Our working rule for clients: audit the programmatic folder quarterly, prune or no-index the bottom quartile by impressions, and reallocate that editorial budget to deepening the top quartile's unique fields.
How do you differentiate near-duplicate comparison pages at scale?
Differentiate with data Google can't source from your competitor's page: your own hands-on test notes, localized pricing or payment rail specifics, a dated screenshot of the actual bonus terms, and a named reviewer's verdict. Templated structure can repeat; the facts inside each cell should not.
The cheapest high-leverage move is localization depth rather than translation. A Brazil-targeted bonus page should reference Pix processing times and BRL minimum deposits specifically, not a generic 'fast deposits' line translated from the English template. That single field change is often enough to break the text-similarity pattern that correlates with the declines we logged.
Second, build a lightweight internal testing log, even a spreadsheet, recording actual withdrawal times, support response times, and KYC turnaround per operator, refreshed on a rolling schedule. Feed that log into the template as a unique field per page. It's genuine first-hand experience (the "experience" pillar of E-E-A-T), and it's data a scraped competitor page literally cannot replicate without doing the same testing.
Third, vary the comparison angle, not just the copy. A "Casino A vs Casino B" page and a "Casino A vs Casino C" page should foreground different comparison dimensions if the operators differ meaningfully, payment speed matters more in one matchup, game library breadth in another. Forcing every comparison through an identical five-criteria grid regardless of relevance is a subtler form of the sameness problem.
What internal linking architecture actually supports programmatic pages?
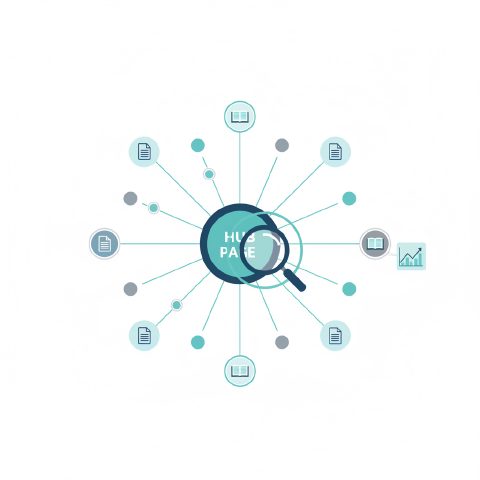
Hub-and-spoke works best in our tracking: one authoritative pillar page per topic (e.g., 'Online Casino Bonuses in Canada') linking out to and receiving links back from every spoke (province-specific or bonus-type pages). Flat, orphaned programmatic folders with no pillar recovered more slowly after core updates in our sample.
Programmatic pages generated purely from a database often ship with weak or absent internal linking, the template engine builds the page but nobody wires it into the site's topical map. That's a mistake our volatility data makes visible: domains where programmatic spokes linked clearly to and from a human-written pillar page regained lost rankings within roughly 6-10 weeks of a core update in several cases we tracked; domains with orphaned or thinly-linked spokes took considerably longer, and some simply never recovered the lost positions within our observation window.
Practically, that means every country or bonus-type spoke needs a breadcrumb back to its category pillar, the pillar needs a genuinely useful (not just a sitemap-style) list of its spokes with one-line descriptors of what differs between them, and related spokes should cross-link where genuinely relevant, a "crypto casino bonuses" spoke linking to a "fastest withdrawal casinos" spoke where the overlap is real, not forced.
This also helps crawl efficiency. Google's crawlers allocate budget partly based on how well-connected a page is within a site's link graph; orphaned programmatic URLs discovered only via XML sitemap tend to get crawled and reassessed less frequently, which slows both initial indexing and post-update recovery.
How should you measure whether a programmatic comparison page set is actually working?
Track three layers together: ranking volatility per URL cohort (not domain average), impression-to-click ratio by query intent in GSC, and citation share in AI answer engines where you can monitor it. A domain average hides which specific template variant is underperforming; cohort-level tracking exposes it.
Segment your rank tracking by template type and market, not just by domain. 'Bonus pages' and 'toplists' behave differently through core updates in our data, and 'UK bonus pages' and 'Brazil bonus pages' on the same domain can move in opposite directions during the same update window because of differing competitive sets and regulatory scrutiny. Ahrefs or SEMrush position tracking tagged by URL pattern makes this segmentation workable at scale.
In Google Search Console, watch impressions holding steady while clicks decline, that combination often signals the page is still being shown but is losing the click to a richer SERP feature (a competitor's table getting pulled into an AI Overview, for instance) rather than losing rankings outright. That's a structured-data and content-depth problem, not a crawling problem.
For AI citation share, manual spot-checking against a fixed query list in Perplexity, ChatGPT browsing mode and Google's AI Overview is currently the most reliable method we have, there's no mature third-party tool giving a verified citation-share percentage yet, and any tool claiming an exact number should be treated skeptically. We log citations weekly against roughly 50 fixed comparison-intent queries per client vertical and track directional change, not absolute percentages.
What are the most common mistakes affiliates make with programmatic bonus pages?
The recurring mistakes in our review work: publishing every mathematically possible page-combination regardless of search demand, batch-faking 'last updated' timestamps, copying a competitor's comparison criteria wholesale, and skipping a named reviewer byline on YMYL financial claims like wagering requirements and withdrawal limits.
Demand-blind generation is the most capital-destructive mistake because it's invisible until you audit impressions. Teams build a combinatorial template generator, let it run across every country, currency and bonus-type intersection their database supports, and end up with thousands of URLs that never earn a single impression, diluting average page quality signals and burning crawl budget for nothing.
Fake freshness signals are the second-most common and, in our view, the easiest to get caught by future algorithmic scrutiny: bulk-updating a timestamp field across hundreds of pages with no substantive content change is trivially detectable via historical crawl diffs, and it signals exactly the kind of low-effort scaled content Google's helpful-content systems were built to discount.
Copying a competitor's comparison grid wholesale, same five criteria, same weighting, no attribution or original reasoning, strips out the one thing that made the original page defensible: a stated, owned methodology. And skipping bylines on pages making specific financial claims (wagering percentages, payout timelines, bonus caps) ignores the YMYL review criteria most directly tied to trust, these are exactly the claims a human reviewer, or an algorithmic system assessing E-E-A-T, expects to see attributed to someone accountable.
Comments
No comments yet, be the first.