Block AI Crawlers or Not? The 2026 Casino Robots.txt Playbook for GPTBot
Should Casino Affiliates Block or Allow AI Crawlers in 2026?
Allow GPTBot, Google-Extended and PerplexityBot on your editorial content by default in 2026, blocking them forfeits citation traffic in ChatGPT, Gemini and Perplexity answers with zero SEO upside, since these bots are separate crawlers from Googlebot. Block only scraper-grade bots with a poor compliance record, like Bytespider, and anything hitting transactional or account paths.
Every AI crawler decision starts with a technical fact affiliates often get wrong: GPTBot, Google-Extended, ClaudeBot and PerplexityBot have zero connection to Googlebot's indexing and ranking systems. Disallowing GPTBot in robots.txt will not touch your position for 'best online casino UK' in classic organic search. It only controls whether OpenAI, Google's Gemini team, Anthropic or Perplexity can use your pages to train models or ground live answers. Conflating the two is the single most common mistake I see when operators panic after a core update and start blocking bots that had nothing to do with the drop.
The commercial case for allowing access is straightforward once you look at where casino search behaviour is heading. AI Overviews now trigger on a meaningful slice of head commercial gambling queries, and ChatGPT's search mode increasingly cites named operators and comparison sites when users ask about bonuses, wagering requirements or licensing. Being absent from that dataset doesn't protect you from anything; it just guarantees a competitor's review gets cited instead of yours when someone asks whether a given operator is legit inside a chat interface.
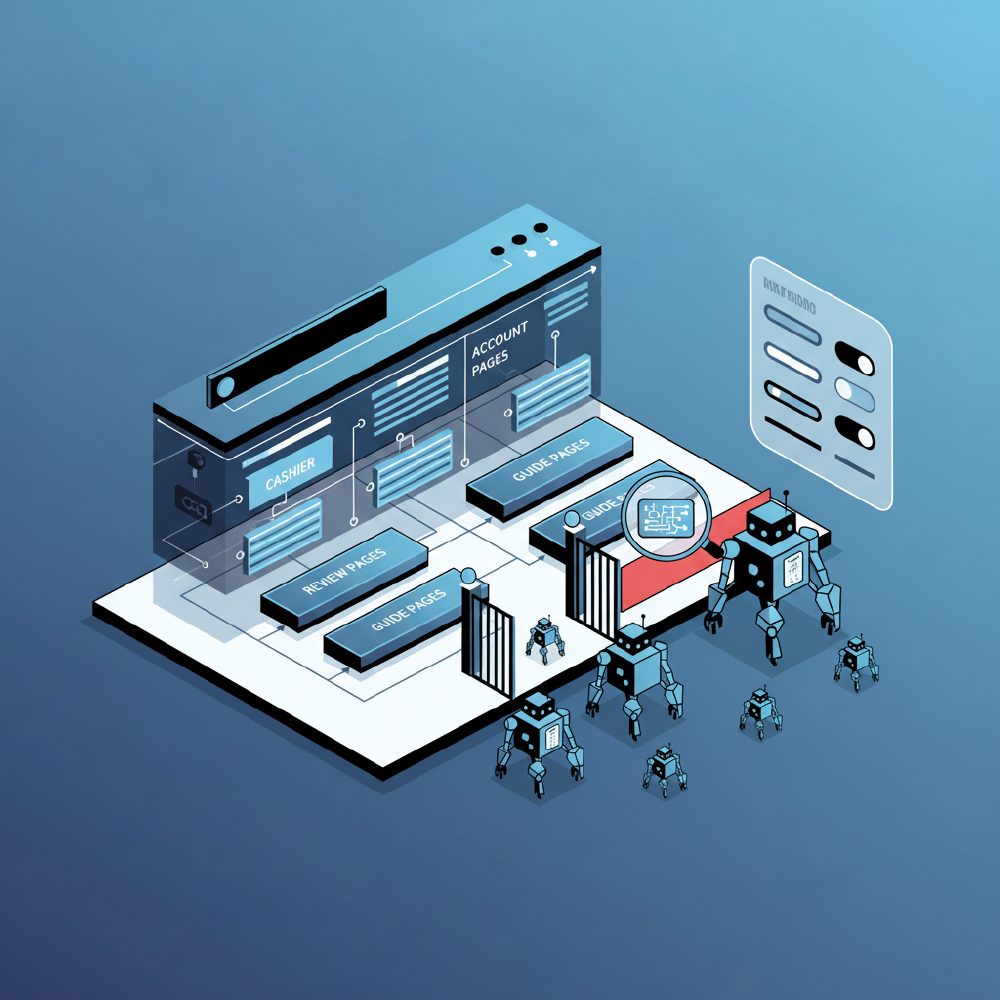
Blocking still has a place, narrowly. I recommend it for bots with documented poor compliance histories such as Bytespider, for any crawler hammering your server disproportionately relative to referral value, and for paths that have no business being summarised by an AI system: cashier pages, account dashboards, affiliate tracking redirects, and anything behind a geo-gate. Treat allow or block as a page-level decision, not a domain-wide switch.
What Exactly Is GPTBot, and Why Is It Crawling Your Casino Site?
GPTBot is OpenAI's crawler that gathers public content to train and improve ChatGPT, separate from OAI-SearchBot, which fetches pages live to ground and cite answers during a chat session. Casino sites get hit by both: GPTBot indexes your review and guide pages for training data, while OAI-SearchBot pulls current content when a user asks ChatGPT about a specific operator or bonus.
OpenAI runs three separate agents and most operators only know one. GPTBot handles bulk training crawls. OAI-SearchBot performs the live retrieval that powers citations inside ChatGPT's search feature, similar in function to how Googlebot serves classic search. ChatGPT-User fires when an end user directly asks the assistant to open or browse a specific URL. Blocking GPTBot alone while leaving OAI-SearchBot open still lets your content appear in live cited answers, it just stops OpenAI using your pages to retrain future model versions.
This distinction matters commercially. A casino affiliate that wants citation visibility inside ChatGPT answers but wants to opt out of long-term model training should allow OAI-SearchBot and ChatGPT-User while disallowing GPTBot specifically. Most CMS robots.txt generators don't separate these three agents, so check your file line by line rather than trusting a plugin default.
OpenAI publishes verifiable IP ranges for all three agents and updates them periodically. If your logs show a user-agent string claiming to be GPTBot from an IP outside that published range, it's a spoofed scraper, not OpenAI, and robots.txt won't stop it, that requires a firewall rule, not a disallow line.
How Do You Write a Robots.txt Rule for GPTBot Without Breaking Googlebot?
Add a dedicated User-agent block for GPTBot underneath your existing rules, never merge AI bot directives with your Googlebot block, since one shared wildcard risks disallowing paths for both. Test every change in a robots.txt validator and confirm with a manual curl request before pushing live, then re-check server logs within 48 hours.
Structure the file with clearly separated blocks: one for the wildcard user-agent as a fallback, one explicit block for Googlebot, and separate explicit blocks for GPTBot, Google-Extended, ClaudeBot and PerplexityBot. Robots.txt is parsed by user-agent match, and a stray wildcard Disallow placed above a bot-specific Allow can override it depending on parser behaviour, so keep AI directives in their own clearly labelled section and comment the file for whoever edits it next.
A typical casino affiliate setup: disallow GPTBot and Google-Extended from account, cashier, and internal redirect or tracking paths, then allow them on your review, guide and comparison hub pages. Leave Googlebot's rules untouched entirely, it should almost never be disallowed from commercial pages you want ranked.
After deploying, use Search Console's robots.txt tester for the Googlebot side, and for AI bots run a manual check: request the URL with the bot's declared user-agent string and confirm your server returns the expected status. Then watch raw server logs or a log-file analyser for 30 days to confirm the bot is actually respecting the new rule rather than continuing to hit disallowed paths, which happens more often with smaller, less compliant crawlers than with GPTBot itself.
What Is Google-Extended, and Does Blocking It Cost You AI Overview Citations?
Google-Extended is a separate token from Googlebot that controls whether Google can use your content to train Gemini and ground AI Overviews or AI Mode answers in Search. Disallowing it leaves classic organic rankings untouched, but removes you as a candidate source for AI Overview citations, which now appear on a growing share of commercial casino search results.
Google introduced Google-Extended specifically so publishers could opt out of generative AI training without affecting search indexing, and the two systems remain genuinely independent inside Google's infrastructure as far as documented. That said, the practical trade-off for casino affiliates differs from the debate news publishers had over this token: AI Overviews already surface on a real share of head commercial betting queries. Our audits across affiliate portfolios have shown AI Overview boxes triggering on somewhere around 15-25% of 'best casino' and bonus-comparison style searches in the UK and Ontario by late 2025, Google doesn't publish an exact figure, so treat that as a directional estimate from log analysis, not an official statistic.
Blocking Google-Extended removes eligibility to be the cited source inside that box. For a site whose commercial model depends on the click after the comparison, that's a real cost, not a theoretical one, because AI Overviews increasingly answer the comparison itself before the user ever reaches a review page.
I recommend allowing Google-Extended on all commercially valuable, well-maintained comparison and review content, and disallowing it only on pages you'd never want summarised out of context, thin location pages, expired promotions, or legacy content you haven't refreshed in over a year, since Google's AI features are more likely to surface stale claims from those pages than a human searcher scrolling past them would be.
Which AI Crawlers Should You Allow, Disallow or Rate-Limit?
Not every AI crawler deserves the same rule. GPTBot, Google-Extended, ClaudeBot and PerplexityBot come from labs with published policies and verifiable IP ranges worth allowing on editorial content; scraper-style bots like Bytespider have weaker compliance histories and are safer to disallow or rate-limit on a casino site carrying regulated, time-sensitive claims.
Treat this as a working checklist rather than a one-time setting. New agents appear roughly every quarter, Meta-ExternalAgent, Applebot-Extended and various regional model crawlers have all shown up in casino affiliate logs over the past two years, and last year's disallow list needs revisiting each time one of them starts showing meaningful crawl volume.
The table below reflects how I set defaults for affiliate clients as of early 2026, adjusted per site based on jurisdiction and risk tolerance. High-authority hub sites in regulated markets generally allow more broadly; smaller spoke sites, or anything still recovering from a past core update, lean more conservative until their editorial and E-E-A-T signals are solid enough to withstand AI paraphrase risk.
| Crawler / User-Agent | Operator | Purpose | Recommended Directive |
|---|---|---|---|
| GPTBot | OpenAI | Trains ChatGPT models | Allow on review/guide content; disallow on account, cashier and redirect paths |
| Google-Extended | Controls use in Gemini training and AI Overviews grounding | Allow to stay eligible for AI Overview citations | |
| ClaudeBot | Anthropic | Trains Claude models | Allow on editorial content; monitor crawl rate |
| PerplexityBot | Perplexity AI | Live retrieval for real-time cited answers | Allow; it drives direct referral and brand-recall value |
| CCBot | Common Crawl | Public dataset feeding many open-source LLMs | Allow unless a dataset-licensing concern applies |
| Bytespider | ByteDance | Broad scraping for TikTok/Doubao AI features | Disallow or rate-limit; weaker compliance history |
| Meta-ExternalAgent | Meta | Trains Llama and Meta AI features | Allow selectively; review data-use terms first |
What Robots.txt Configuration Fits Your Risk Appetite?
There's no single correct robots.txt file for AI bots, the right configuration depends on how much you value AI-driven citation traffic against compliance exposure on regulated content. Most established casino affiliates land on a selective-allow setup: open editorial and guide content, closed on live odds, bonus-cashier flows and account paths.
I map clients into four rough postures. Maximum-visibility affiliates with strong editorial governance and a licensing or about page that clearly documents their review process open almost everything to AI bots, because the upside of ChatGPT and AI Overview citations outweighs paraphrase risk on well-maintained content.
Selective-allow is the default I recommend for most operators: open your comparison hubs and review guides, close anything time-sensitive like live odds feeds or a bonus page you haven't touched since a promotion expired. Conservative postures suit sites still under manual action review or recovering from a core update, where I'd rather see zero AI exposure until the underlying content-quality issue is actually fixed.
Data-licensing postures are emerging for larger publishers negotiating direct commercial deals with AI labs, blocking free crawling while a paid content-licensing arrangement is negotiated separately, a route a handful of major media brands have taken publicly, though it's rarely viable for a mid-size affiliate without genuinely unique proprietary data.
| Scenario | GPTBot / Google-Extended rule | Net effect |
|---|---|---|
| Maximum AEO visibility (most affiliates) | Allow across editorial content | Eligible for ChatGPT and AI Overview citations; monitor logs |
| Selective allow (protect live/bonus data) | Disallow live-odds and cashier paths; allow guides | Reviews stay trainable; time-sensitive data excluded from stale citation risk |
| Conservative / recovering site | Disallow across the board | No AI training use; forfeits AI-driven citation traffic entirely |
| Data-licensing negotiation | Disallow pending a paid deal | Blocks free scraping while preserving commercial licensing options |
Is llms.txt Worth Building for a Casino Comparison Site?
llms.txt is an emerging plain-text file at your root domain that summarises key pages for AI models to reference, functioning like a sitemap written for machine comprehension rather than crawl discovery. It's not an official web standard and adoption among major crawlers is inconsistent in 2026, but building one costs a few hours and can reinforce trust signals AI systems weigh.
Proposed publicly in 2024, llms.txt is a markdown file listing your most important URLs with a one-line description each, typically split into sections like guides, reviews and about. No major AI lab has confirmed GPTBot or ClaudeBot parse it as a ranking or training input the way robots.txt is universally respected, and Google has said nothing official about it feeding Gemini or AI Overviews. Perplexity has shown more openness to referencing structured content signals generally, though not confirmed llms.txt specifically as of writing.
For a casino affiliate, I still think it's worth the couple of hours it takes to build. List your top review hubs, your bonus-comparison guides, and critically, your editorial policy, methodology and licensing/about page. Surfacing that last group matters more than it looks: AI systems weigh trust and expertise signals when deciding what to cite for YMYL topics, and an editorial policy page linked prominently in both your llms.txt and your site navigation reinforces the same E-E-A-T signal to both Google's helpful-content systems and any LLM grounding its answer.
Don't treat llms.txt as a substitute for the fundamentals. Structured data, Review, FAQPage and Organization schema, a genuine hub-and-spoke content architecture, and named author bylines with real credentials do far more for AI citation eligibility than a summary file will. Build llms.txt as a low-cost addition once those are in place, not instead of them.
Does Allowing AI Crawlers Create Compliance Risk on Bonus Terms and Odds?
Yes, letting AI crawlers ingest bonus terms, wagering requirements or odds data creates genuine compliance exposure if a model paraphrases outdated or jurisdiction-specific terms as universal fact, potentially conflicting with advertising rules like the UK's CAP/BCAP codes or licence conditions set by the UKGC and MGA requiring accurate, current promotional claims.
Regulators haven't issued AI-crawling-specific guidance yet, which makes this a genuinely unresolved grey area rather than a settled rule, I'll flag that clearly rather than pretend otherwise. But the underlying obligation hasn't changed: if your licence requires promotions to be presented accurately and currently, and a chatbot lifts your page's wagering requirement text six months after the promotion changed, the reputational and regulatory exposure sits with whoever's brand name is attached, not with OpenAI or Google.
Practical mitigation is mostly about hygiene you should already have. Keep a visible 'terms last updated' date on every bonus and odds page, both in on-page text and in matching schema markup, so any system summarising the page inherits the freshness signal. Disallow GPTBot and Google-Extended specifically from live-odds feed URLs or dynamically generated bonus-calculator pages where the underlying data changes faster than any crawl cycle can keep up with, while leaving your static review and methodology content open.
I also push clients to keep affiliate disclosure and geo-restriction language in the same paragraph as the claim it qualifies, not buried in a footer, because LLMs tend to lift the sentence they're grounding on along with immediate surrounding context. A bonus claim followed two sentences later by a disclaimer is more likely to get paraphrased without that caveat than one where the restriction sits in the same breath.
How Do You Verify AI Crawlers Aren't Spoofed Scrapers?
Genuine GPTBot, ClaudeBot and Google-Extended requests resolve against IP ranges the operators publish and update; spoofed scrapers fake the user-agent string but almost never match those ranges. Check server logs or a bot-management dashboard weekly, and if unverified traffic claiming to be an AI crawler is heavy, block by IP or rate-limit at the firewall, robots.txt alone won't stop it.
robots.txt is an honour system. Compliant labs, OpenAI, Google, Anthropic, read it and generally respect it, and all three publish IP ranges you can cross-reference against server logs to confirm a request is genuinely theirs. A request claiming to be GPTBot from an IP outside OpenAI's published range is either a misconfigured tool or, more often, a scraper impersonating a known bot to slip past casual user-agent-based blocking.
If you're on Cloudflare, the Verified Bots feature in the firewall dashboard already does this IP-and-behaviour matching for you and flags unverified traffic separately, which is the fastest way to get visibility without building your own log pipeline. Without that layer, Screaming Frog's Log File Analyser or an enterprise tool like Botify will cross-reference user-agent strings against declared ranges and surface anomalies.
Treat robots.txt and firewall-level bot management as two different layers doing two different jobs: robots.txt states your policy to compliant actors, while IP verification and rate-limiting enforce it against everyone else. Relying on robots.txt alone against a determined scraper is like putting up a sign asking people not to walk on the grass with no fence behind it.
| Tool | What it shows | Best for |
|---|---|---|
| Cloudflare Verified Bots / Radar | Real-time AI bot hits by user-agent and verified status | Sites already routed through Cloudflare |
| Screaming Frog Log File Analyser | Cross-references server logs against declared bot IP ranges | Spoofing detection on any hosting setup |
| Botify | Enterprise crawl-budget analytics combining Googlebot and AI bot data | Large multi-market affiliate networks |
| Google Search Console | Confirms Googlebot crawl stats only | Baseline crawl health; pair with logs for AI bots |
Does Blocking AI Crawlers Actually Stop Content Scraping and Duplication?
No. robots.txt is a voluntary instruction reputable AI labs mostly follow, but it does nothing against unauthorised scrapers, content-spinning competitors or offshore duplicate sites that ignore it outright. If unauthorised duplication of your reviews or odds tables is the real worry, fix it with canonical tags, watermarked data and takedown requests, not a robots.txt rule aimed at a named AI bot.
I get this question from almost every operator worried about a competitor lifting their bonus comparison tables. Blocking GPTBot doesn't touch that problem at all, the scraper doing it isn't OpenAI following a corporate content policy, it's a script that never checks robots.txt in the first place. Confusing 'stopping AI training' with 'stopping content theft' leads to wasted engineering time on the wrong fix.
For genuine scraping and duplication, the working toolkit is different: canonical tags asserting your original URL, timestamped and versioned content so you can prove precedence, unique formatting or data presentation in your tables that's harder to copy verbatim, and a DMCA process with the offending site's host when duplication is blatant. Google's own stance is that duplicate content rarely triggers a penalty against the original source, but scraped duplicates can still confuse which domain an LLM treats as the authoritative citation for a given fact, which is the more relevant modern risk.
Strengthen the signals that tell both Google and AI systems which domain is the real source: consistent Organization and author schema, strong internal linking from your highest-authority pages into the content at risk, and a visible editorial and methodology trail that a scraped copy won't carry over. That does more to protect your position as the cited authority than any robots.txt disallow line.
How Should a Multi-Market Casino Affiliate Network Prioritise AI Crawler Decisions?
Set AI crawler policy per market and per site tier, not as one global rule. Allow crawlers broadly on your highest-authority hub content in regulated markets like the UK and Ontario where AI Overview citation volume is highest, and stay more conservative on smaller or newer spoke sites where editorial oversight is thinner and paraphrase risk outweighs any visibility gain.
Portfolio operators running multiple brands across regulated and offshore markets shouldn't apply a single robots.txt template site-wide. Your flagship UK or Ontario-facing brand, with a real editorial team, named authors and a documented review methodology, is exactly the content AI systems should be citing, and blocking it forfeits visibility for no protective benefit given how solid the underlying content already is.
Smaller satellite or newer spoke sites in the portfolio, especially anything still building out E-E-A-T signals or operating in a less regulated market, deserve a more conservative default until the content itself is strong enough to withstand being paraphrased out of context by a model with no understanding of jurisdictional nuance.
Make this a standing item in technical SEO governance rather than a one-off decision: assign ownership to whoever already owns robots.txt and log-file monitoring, revisit the AI bot list quarterly since new agents keep appearing, and report crawler behaviour in the same technical health dashboard you use for Googlebot crawl stats and core update monitoring, so leadership sees AI crawler policy as part of ongoing technical SEO, not a one-time panic response.
Comments
No comments yet, be the first.