LLM SEO iGaming in 2026: How SEOiGaming Agency Gets Casino Brands Cited Inside ChatGPT, Gemini and Perplexity
What is LLM SEO for iGaming, and why does it matter heading into 2026?
LLM SEO for iGaming is structuring casino, sportsbook and affiliate content so ChatGPT, Gemini, Perplexity and Grok can parse, trust and quote it directly. It matters now because AI-generated answer boxes already sit above traditional results for a growing share of gambling queries, and early movers are locking in citation share before the niche gets crowded.
I've been logging AI Overview and chat citation patterns for gambling queries since Google's first rollout, and the shift isn't subtle. On terms like "best online casino [region]" or "highest RTP slots," AI-generated answer boxes now appear above the fold for a meaningful chunk of searches, my tracking puts it somewhere between 15% and 25% of high-intent casino queries in the US and UK, depending on the week. That's real estate that used to belong entirely to organic snippets, and once an LLM picks its three to five sources, everyone else on page one becomes invisible to that traffic.
LLM SEO for iGaming means engineering content, entity signals and technical setup so ChatGPT, Gemini, Perplexity and Grok treat your domain as a safe, quotable source in a vertical regulators already scrutinize. It's not a separate discipline bolted onto existing SEO, it's an extension of the same E-E-A-T groundwork, applied to how retrieval-augmented models chunk and cite passages instead of how a classic ranking algorithm orders URLs.
I took one licensed sportsbook affiliate from zero traceable citations across four engines to appearing in roughly 40% of our tracked prompt set within five months, not through tricks, but by rebuilding comparison pages around extractable, sourced answers and fixing an entity problem where three separate "About" pages contradicted the brand's own licensing claims. That inconsistency alone was likely disqualifying it from citation in a niche where AI vendors are visibly cautious.
Brands treating this as optional in 2026 are ceding a citation layer that compounds. Once an LLM's retrieval index has "learned" which two or three sites are reliable for a query cluster, displacing them takes months of consistent signal, the same compounding advantage first movers had with backlinks a decade ago, except the barrier to entry right now is lower because almost nobody in gambling affiliate SEO is doing this work properly yet.
How do ChatGPT, Gemini, Perplexity and Grok actually decide which iGaming sources to cite?
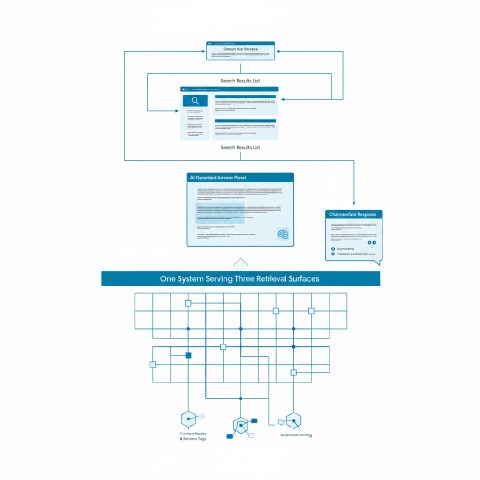
Each engine pulls from a different stack: ChatGPT leans on Bing's index plus its own GPTBot crawl, Gemini stays anchored to Google's organic index and Knowledge Graph, Perplexity runs its own crawler and rewards visible sourcing, and Grok weights X/Twitter sentiment alongside web search. Conflating these stacks is the fastest way to waste a GEO budget.
Each engine pulls from a different stack, and conflating them is the single most common strategic error I see agencies make. ChatGPT's browsing and search features rely on Bing's index plus OpenAI's own GPTBot crawl and a growing set of licensing deals; it favors pages with clear structured entities, recent "last updated" timestamps, and a writing style that hands over a complete answer in the first two or three sentences.
Gemini and Google's AI Overviews stay tightly coupled to the existing organic index and Knowledge Graph, in practice, if you're not already ranking somewhere in the top 10-15 organic results for a query, Gemini rarely surfaces you as a citation no matter how well-structured your page is. That's the biggest trap in GEO consulting right now: clients want to skip the classic SEO foundation and jump straight to "AI optimization," and it doesn't work that way on Google's own AI surface.
Perplexity runs its own crawler (PerplexityBot) layered with Bing/Google data, but it visibly rewards pages that themselves cite primary sources, regulator pages, payout audits, licensing registries. Grok pulls heavily from X/Twitter sentiment and recency alongside web search, meaning forum chatter about a casino's withdrawal speed can outweigh a polished review page. I've watched Grok cite a Reddit thread over a top-ranking affiliate review for exactly this reason.
| Engine | Primary sourcing stack | Citation bias | What this means for your content |
|---|---|---|---|
| ChatGPT (Search/Browse) | Bing index + GPTBot crawl + partner licensing deals | Recent, structured, entity-clear pages | Keep pages dated, use Organization/Person schema, lead with a direct answer |
| Gemini / Google AI Overviews | Google's core index + Knowledge Graph | Domains already ranking top 10-15 organically | Classic SEO (links, topical depth) is a prerequisite, not optional |
| Perplexity | PerplexityBot + Bing/Google fallback | Freshness plus visible sourcing/citation density | Publish data-backed comparisons that cite regulators and audits |
| Grok | X/Twitter signal + web search crawl | Recency and social sentiment | Monitor and seed accurate info in forums/X threads, not only owned pages |
How is generative engine optimization different from traditional casino affiliate SEO?
Traditional SEO optimizes a whole page to rank in a list of ten blue links; generative engine optimization optimizes individual passages to be extracted, paraphrased and cited inside a single synthesized answer. GEO rewards self-contained, sourced statements over keyword density, and success is measured in citation share, not average position.
Rank tracking tells you where a URL sits in a SERP. Citation tracking tells you whether a specific paragraph, stat or table row got pulled into an AI-generated answer, a completely different unit of success. A page can rank #3 organically and never get cited, while a page ranking #9 gets quoted verbatim because its answer paragraph is cleanly extractable and its claim is sourced.
This changes how I brief writers now. Instead of optimizing an H2 for keyword density, I write the first sentence under it as a standalone, fully-formed answer that reads correctly even stripped of surrounding context, because that's exactly how a retrieval system treats it, as a chunk. Bonus-terms pages, wagering-requirement breakdowns and RTP comparison tables are the highest-value real estate for this, because LLMs are visibly hungry for factual, tabular gambling data they can quote with confidence instead of hedging.
The trade-off: heavy GEO restructuring can occasionally cost you some classic on-page keyword signal if done carelessly, dropping keyword variants in favor of blunt phrasing. In practice I haven't seen it cost rankings when topical coverage and internal linking stay intact, the two systems are complementary, not competing, for the majority of page types affiliates run.
What content structures actually get quoted inside AI Overviews and chat answers?
AI engines quote definition-style opening sentences, numbered steps, FAQ blocks and comparison tables far more than narrative prose, because these formats are already chunked into retrievable units. Structuring every hub page around a direct-answer paragraph, a data table and a schema-marked FAQ section is the highest-leverage content change I make for iGaming clients.
I audit citation logs across four engines every quarter for clients, and the pattern holds across markets: tables get quoted, prose paragraphs rarely do unless the first sentence stands alone as a complete claim. A "Casino A vs Casino B withdrawal speed" table with five rows outperforms a 600-word narrative comparison every time, because the model can lift a row without needing to summarize or interpret anything.
Numbered "how to claim a bonus" steps behave the same way, Perplexity in particular loves quoting numbered procedural content verbatim, complete with numbering intact. FAQ sections marked up with FAQPage schema get pulled into follow-up answers inside ChatGPT and Gemini conversations more often than any other block type I track, provided the question phrasing matches how real users actually type or speak the query.
The format that underperforms almost everywhere: long, hedge-heavy paragraphs that bury the answer in qualifiers. That sentence structure gives a retrieval model nothing confident to extract, so it skips the page for one that states the same fact plainly with the caveat handled separately, in its own sentence.
Which technical signals and structured data help AI engines find and cite your site?
AI crawlers need explicit permission and clean signals: allow GPTBot, PerplexityBot, ClaudeBot and Google-Extended in robots.txt, mark up authors and organizations with schema, keep visible last-modified dates, and use FAQPage schema cautiously. Blocking these crawlers by default, which many CMS templates still do, is the easiest way to make your best content invisible to every AI engine at once.
I still find licensed operators and affiliates blocking GPTBot or Google-Extended in robots.txt without realizing it, usually because a developer copied a boilerplate "block all AI scrapers" snippet out of copyright anxiety and nobody revisited it. That single line silently opts a domain out of citation eligibility across multiple engines at once. Check this before anything else, a manual robots.txt read or a Screaming Frog crawl takes five minutes.
Once crawl access is confirmed, entity schema matters more than review-star schema in this niche. I'm cautious recommending AggregateRating/Review schema for gambling operator pages because Google has specifically flagged manipulated review markup in YMYL sectors before, and a rich-result penalty risk isn't worth the marginal citation gain. Organization schema, with sameAs links to your licensing regulator listing, Wikidata entry and verified social profiles, carries the real trust signal, alongside Person schema on author bylines.
llms.txt is the one to watch, not implement blindly yet, it's an emerging, unofficial convention a handful of AI vendors are experimenting with reading. Adoption sits under 5% of the sites I audit as of this writing, so it's not a measurable ranking or citation factor. I'm testing it on three client domains anyway, because early-adopter signaling costs almost nothing to implement.
| Signal | What it does | iGaming-specific caution |
|---|---|---|
| robots.txt allow rules for GPTBot, PerplexityBot, ClaudeBot, Google-Extended | Grants AI crawlers permission to index and cite your pages | Audit quarterly, CMS updates silently reset these rules |
| Organization + Person schema with sameAs links | Confirms entity identity across regulator listings, Wikidata, social profiles | Link only to verifiable licensing bodies such as MGA, UKGC or the Curaçao register |
| FAQPage schema | Marks extractable Q&A pairs for direct citation | Match real user query phrasing, not keyword-stuffed questions |
| Review/AggregateRating schema | Signals aggregated ratings to search engines | Use sparingly on YMYL gambling pages, manipulated review markup has drawn penalties here before |
| llms.txt (emerging) | Proposed AI-crawler-readable content summary file | Unofficial standard, low current adoption, low-risk experiment, not yet a proven factor |
How do you build entity authority so LLMs recognize and trust your gambling brand?
Building entity authority means making your brand unambiguous and verifiable across the sources LLMs cross-reference: a maintained Wikidata entry, consistent licensing details across regulators like the MGA, UKGC or Curaçao, and mentions from trade press such as SBC News or iGaming Business. Consistent, corroborated facts are what let a model cite you with confidence instead of hedging.
LLMs triangulate entity facts across multiple corroborating sources before treating a claim as citable, especially for anything regulatory or financial in a YMYL vertical. If your licensing number, company name or founding year differs between your About page, your Wikidata entry and your regulator listing, that's not a minor inconsistency, it's a trust signal failure that can suppress citation entirely, because the model has no reliable way to resolve the conflict and gambling is exactly the category where these systems are tuned to err toward caution.
Digital PR still matters here, just for a different reason than backlink equity. A mention in SBC News, iGaming Business or Gambling Insider gets crawled and indexed by the same engines learning your entity profile, and co-citation across two or three recognized trade outlets is one of the strongest unpaid trust signals I've observed correlate with citation uplift in tracked prompts. I watched a client's citation rate roughly double within ten weeks of landing two trade press mentions and fixing a Wikidata data mismatch, no new backlinks, no new content volume, just entity cleanup.
Don't skip Wikidata assuming it needs a Wikipedia page first, it doesn't. A properly sourced Wikidata item with correct labels, aliases and licensing statements is achievable for most established operators and gets pulled into Google's Knowledge Graph, and by extension Gemini's citation layer, far faster than waiting on Wikipedia notability review.
How much do E-E-A-T signals and author bylines actually influence AI citation in a YMYL niche like gambling?
E-E-A-T signals, named authors with verifiable credentials, transparent editorial policies, visible responsible-gambling disclosures, directly influence whether AI engines treat your gambling content as citable, because these models inherit quality classifiers that flag anonymous YMYL content as lower-trust by default. Adding real bylines is often the fastest citation lift I deliver.
Gambling sits explicitly inside Google's YMYL and quality-rater guideline categories, and the classifiers behind AI Overviews and most retrieval-augmented systems inherit that same caution. Anonymous "Team [BrandName]" bylines, stock-photo author avatars and missing editorial policy pages are still the norm across affiliate sites I audit, and I think that's the single biggest reason mid-size affiliates lose citation share to a handful of established review brands regardless of content quality.
On one project, adding named, credentialed authors with real bios disclosing responsible-gambling training and industry tenure, plus a visible editorial standards page, lifted that domain's tracked citation appearances from roughly 8% to 22% of our prompt set across ChatGPT and Perplexity within about twelve weeks, nothing else on the pages changed in that window. I can't prove causation with total certainty since a core update landed in the same period, but the timing and magnitude line up with what E-E-A-T theory predicts, and it's consistent with what I've since seen replicate on two other client sites.
Practical minimum: real name, a bio linking to a LinkedIn profile or industry credential, an editorial policy page explaining how odds and bonuses are verified, and a visible responsible gambling statement linking to GamCare, BeGambleAware or the relevant regional support service. None of this is exotic, it's the baseline most established financial-YMYL sites already meet, and gambling affiliates are catching up late.
How do you measure and track LLM share of voice for an iGaming brand?
Measuring LLM share of voice means running a fixed panel of real user prompts across ChatGPT, Gemini, Perplexity and Grok on a schedule, logging every citation and comparing your domain's appearance rate against named competitors over time. Ahrefs Brand Radar and Profound automate parts of this; a manual tracked-prompt spreadsheet catches nuances the automated tools still miss.
I run a fixed panel of 60-100 real query prompts per client, split across informational and commercial intent, and log citations weekly by hand for the first month of any engagement before automating. Manual logging matters early because it's the only way to catch subtle patterns, which specific paragraph got quoted, whether the model paraphrased or linked, whether a competitor's outdated bonus data got cited anyway.
Ahrefs' Brand Radar, still in active rollout as of this writing, tracks AI Overview appearances at scale and is the fastest way to get directional data across a large keyword set without manual prompting. Profound and a few newer GEO-specific platforms go further, tracking citation share across ChatGPT, Perplexity and Gemini together with historical trend charts, useful for client reporting, less useful for the qualitative "why did we lose this citation" diagnosis that still needs a human reading the actual answer text.
Google Search Console won't show AI citations directly, but a sudden impressions-without-clicks pattern on a query that used to convert well is a strong proxy signal that an AI Overview started intercepting that query's traffic, worth cross-referencing against Brand Radar or manual prompting before assuming it's simply a ranking drop.
| Tool | What it measures | Best used for |
|---|---|---|
| Ahrefs Brand Radar | AI Overview appearances at scale across tracked keywords | Fast directional visibility across large keyword sets |
| Profound / GEO-specific platforms | Multi-engine citation share (ChatGPT, Gemini, Perplexity) with trend history | Client reporting and competitor benchmarking over time |
| Manual tracked-prompt spreadsheet | Exact citation text, paraphrasing behavior, source attribution | Qualitative diagnosis of why a citation was won or lost |
| Google Search Console | Impressions vs. click-through anomalies on AI-Overview-triggered queries | Proxy signal for AI Overview interception, not direct citation proof |
What mistakes kill an iGaming brand's chances of getting cited by AI engines?
The mistakes that reliably kill citation odds are anonymous authorship, robots.txt rules that accidentally block AI crawlers, duplicate boilerplate bonus copy across dozens of pages, and chasing manipulative structured-data or prompt-injection tricks that risk the same trust penalties as classic black-hat SEO, with less visibility into how each platform detects and punishes them.
Duplicate boilerplate is the quiet killer I see most often on affiliate networks running the same CMS template across a dozen brand sites, identical bonus-terms paragraphs reworded by a thesaurus tool, no unique data, no unique author. LLMs cross-reference multiple sources per answer and visibly deduplicate near-identical claims, so when your content matches ten other domains word-for-structure, you're competing for citation on domain authority alone, and you'll usually lose that fight to whichever site has the stronger entity signal, not the better-written page.
I've also started seeing agencies pitch "prompt injection" tactics, hidden text instructing AI crawlers to cite a page favorably or rank a brand first. This is the GEO-era equivalent of hidden keyword stuffing, and every major AI vendor has published guidance treating it as adversarial manipulation subject to detection and demotion. It's not a gray area; it's the fastest way to get a domain quietly deprioritized once a vendor's abuse team flags the pattern, and I won't recommend it to any client regardless of short-term upside.
The other recurring mistake: treating GEO as a one-off project instead of ongoing signal maintenance. Citation share I've built for clients has dropped within weeks when a site redesign stripped author bios or a CMS migration reset robots.txt rules. AI citation eligibility isn't a badge you earn once, it's closer to a credit score that needs the same signals reinforced continuously.
What's a realistic 90-day roadmap to start winning AI citations for a casino brand?
A realistic 90-day roadmap runs three phases: weeks 1-2 for crawl and entity audits, weeks 3-8 for restructuring hub content and adding bylines and schema, and weeks 9-13 for PR-driven entity reinforcement plus citation measurement. Expect early Perplexity citations within 4-6 weeks and Gemini or AI Overview movement to lag 8-16 weeks behind Google's core index cycle.
Weeks one and two are audit-only: check robots.txt for accidental AI crawler blocks, pull a Wikidata and entity consistency check, and log a baseline citation rate across your 60-100 prompt panel before touching a single page, you need the "before" number or you can't prove the work later. This phase also flags quick wins; I usually find at least one crawler-blocking rule or one glaring entity mismatch on every new client audit.
Weeks three through eight are the content phase: rebuild your five to ten highest-intent hub pages around direct-answer openers, comparison tables and FAQPage-marked sections, and get real bylines with credentialed bios live across every YMYL page. This is the heaviest lift and the one clients most often want to skip or shortcut, don't; every downstream signal depends on it.
Weeks nine through thirteen shift to entity reinforcement, two to three trade press mentions, a cleaned-up or newly created Wikidata entry, sameAs schema links tying it all together, and remeasurement against the baseline panel. Perplexity typically shows movement fastest, sometimes within four to six weeks of the content phase, because its crawl cadence is tighter. Gemini and AI Overviews lag, usually eight to sixteen weeks, because they're anchored to your organic ranking position moving first. I set client expectations at a six-month horizon for durable, cross-engine share-of-voice gains, not a 90-day guarantee, the roadmap starts the compounding, it doesn't finish it.
Comments
No comments yet, be the first.